Invisible Text Exposes an AI Security Boundary Gap
Invisible Text Exposes an AI Security Boundary Gap
Assumption to Challenge
Most security architectures treat rendered text as the truth. If an email, retrieved document, or tool description looks harmless to a person and passes a content filter, leaders assume downstream systems are evaluating the same meaning.
That assumption is now unsafe. Thesis: enterprise AI security must govern text canonicalization and semantic equivalence as a shared boundary control, because people, parsers, tokenizers, models, detections, and audit systems can interpret the same text differently.
Why It Breaks Now
Microsoft's September 2026 research showed attackers inserting invisible Unicode tag characters inside financial lure words. The message still looked normal, but literal and token-based analysis could receive a different sequence. Microsoft observed its tuned signature jump from roughly 21,000 hits to more than 1.3 million in one day, later peaking above 2.3 million. Layered protections caught most messages; the important signal is that an AI-era prompt-injection technique crossed into high-volume phishing evasion.
The risk extends beyond email, but the controls do not transfer unchanged. The Cloud Security Alliance documents hidden Unicode instructions in agent skills and tool metadata. OWASP notes that prompt injection can be imperceptible to people and can arrive indirectly through external content. A RAG pipeline, coding agent, email gateway, and identity system each has different parsers and consequences. Their common failure is unmanaged representation change.
Strategic Reframe
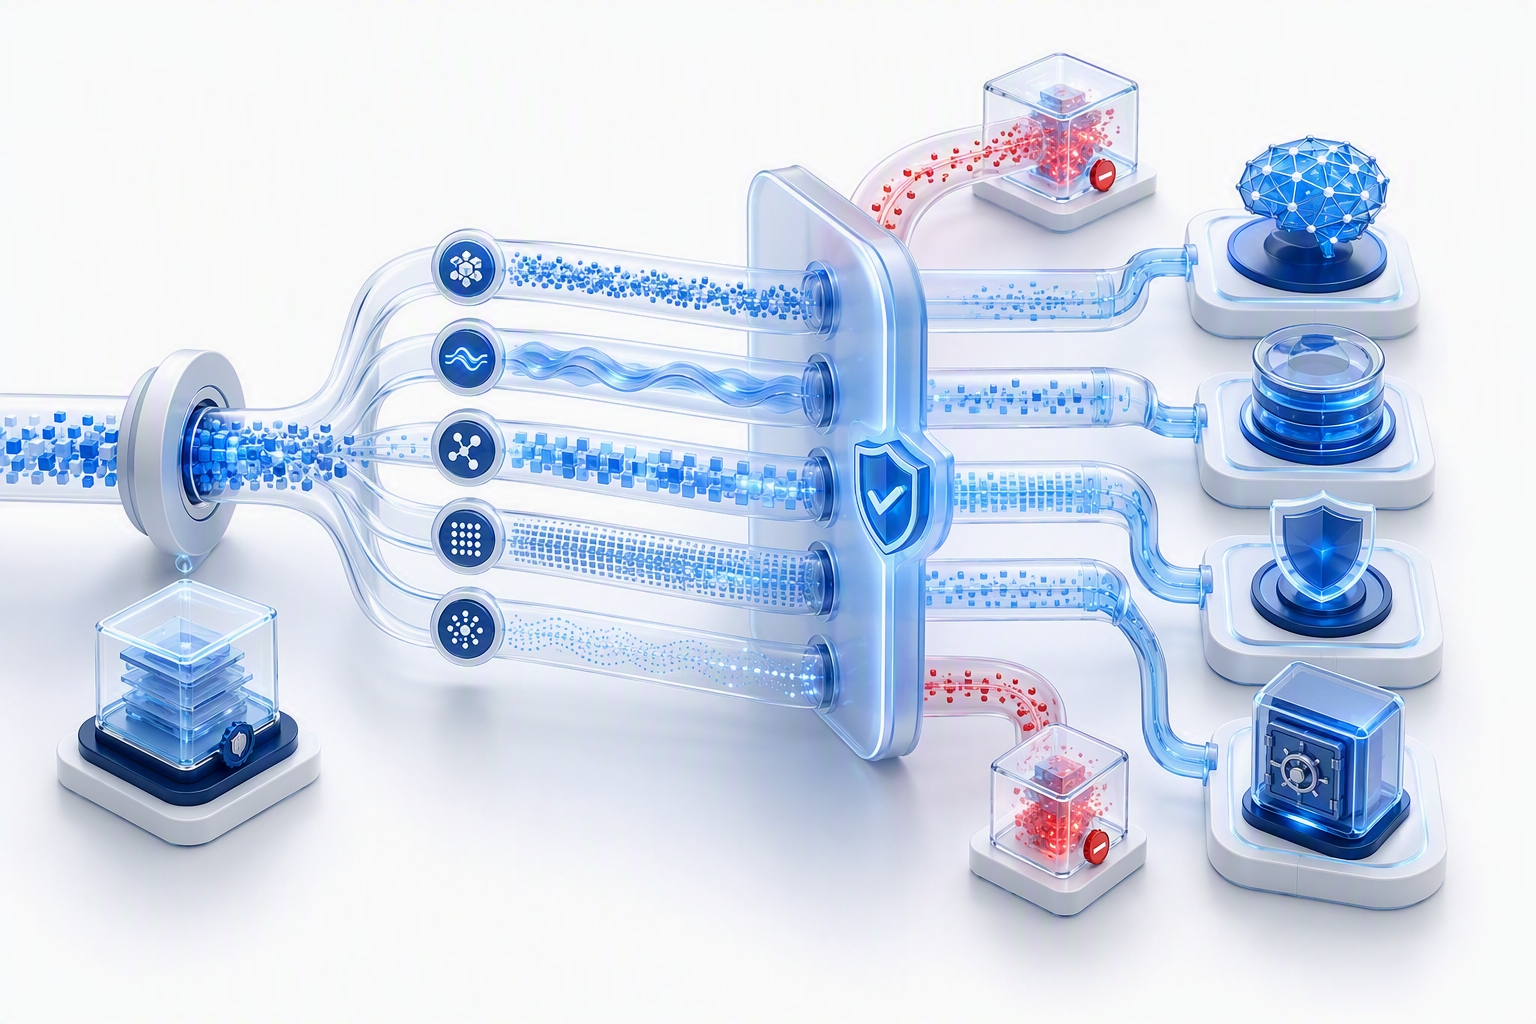
Canonicalization is not a string-cleaning task owned by one development team. It is a security contract defining which representation each control evaluates, which transformations are permitted, and which evidence survives. Semantic equivalence then asks whether intentionally different representations still carry the same authorized meaning, using deterministic schemas or secondary evaluation where risk justifies it.
Unicode Technical Standard #39 provides useful mechanisms for identifier security, confusables, and mixed scripts. It is not a universal policy for free-form documents. Enterprises still need pipeline-specific rules for prompts, retrieved content, tool metadata, identifiers, and logs. High-risk AI boundaries also need visibility into the representation sent to the model and tokenizer output where a provider exposes it; managed-provider opacity remains a residual risk.
Decision Choices and Trade-offs
Blanket removal of unusual characters is simple and reduces some evasions. It can also damage legitimate multilingual text, identifiers, accessibility content, and emoji sequences. Preserving every input unchanged protects fidelity but lets visually identical content travel through controls with different machine meaning.
The recommended balance is risk-tiered. Use lightweight raw-versus-normalized checks inline where a decision must be fast. Reserve full comparison of raw, rendered, normalized, tokenized, and logged forms for high-impact workflows or asynchronous investigation. Always retain the raw representation as forensic evidence.
The trade-off is operational simplicity versus semantic assurance. More representations create cost and complexity; fewer leave leaders unable to prove that a security decision was made on the content a model actually consumed.
Recommended Stance and First Executive Move
Adopt one enterprise canonicalization policy with pipeline-specific profiles, accountable owners, explainable exceptions, and preserved raw evidence. Treat representation drift as a measurable control failure, not a parser quirk.
This week, select one high-impact ingestion path and create a representation-difference map. Compare what entered, what a person saw, what normalization produced, what reached the model, and what the audit trail retained. Treat third-party extractors as explicit transformation boundaries. Assign an owner to every transformation. Where two controls make decisions on different representations without an explicit reason, fund the gap before increasing AI autonomy.
Brewed Insight
If your audit trail cannot reconstruct what the model interpreted, it records an interface - not the security truth.
Sources
- Microsoft Security Blog, "ASCII smuggling crosses over from AI prompt injection to phishing evasion": https://www.microsoft.com/en-us/security/blog/2026/09/03/ascii-smuggling-crosses-over-from-ai-prompt-injection-to-phishing-evasion/
- Cloud Security Alliance, "Hidden Unicode Instruction Injection in AI Agent Skills": https://labs.cloudsecurityalliance.org/research/csa-research-note-unicode-instruction-injection-ai-skills-20/
- OWASP GenAI Security Project, "LLM01:2025 Prompt Injection": https://genai.owasp.org/llmrisk/llm01-prompt-injection/
- Unicode Consortium, "Unicode Technical Standard #39: Unicode Security Mechanisms": https://unicode.org/reports/tr39/
- "Reverse CAPTCHA: Evaluating LLM Susceptibility to Invisible Unicode Instruction Injection": https://arxiv.org/abs/2603.00164